

Full Usage Guide
Downloading GGG Profiles
Section titled “Downloading GGG Profiles”This pipeline automates the process of obtaining atmospheric profiles described in the Ginput documentation. Configure the FTP email address under ggg_profiles_downloader.server.email and the requested date range, models, and locations under ggg_profiles_downloader.scope.
Run the following command to download all the profiles:
python cli.py ggg_profiles_downloader runThe downloader uses the metadata and configured local profiles directory to determine which profiles are missing. Each run requests missing profiles and checks the results of ongoing requests.
This process ensures that only ggg_profiles_downloader.server.max_parallel_requests queries run simultaneously. It only requests the same profiles again if they have not been generated within 24 hours. The downloader can also handle partial query results, such as five fulfilled days from a seven-day request.
Use ggg_profiles_downloader.ggg2020_standard_sites to configure pre-generated GGG2020 standard-site data. The downloader fetches these profiles directly instead of submitting generation requests for them.
Run the following to request the current queue status of your account:
python cli.py ggg_profiles_downloader request-ginput-statusRunning Retrievals
Section titled “Running Retrievals”Use the following commands to start the retrievals in a background process.
python cli.py retrieval startYou can limit the number of concurrent retrieval processes using retrieval.general.max_process_count.
Using the following commands, you can check whether the retrievals are still running and open a dashboard to monitor the progress.
python cli.py retrieval is-runningpython cli.py retrieval watch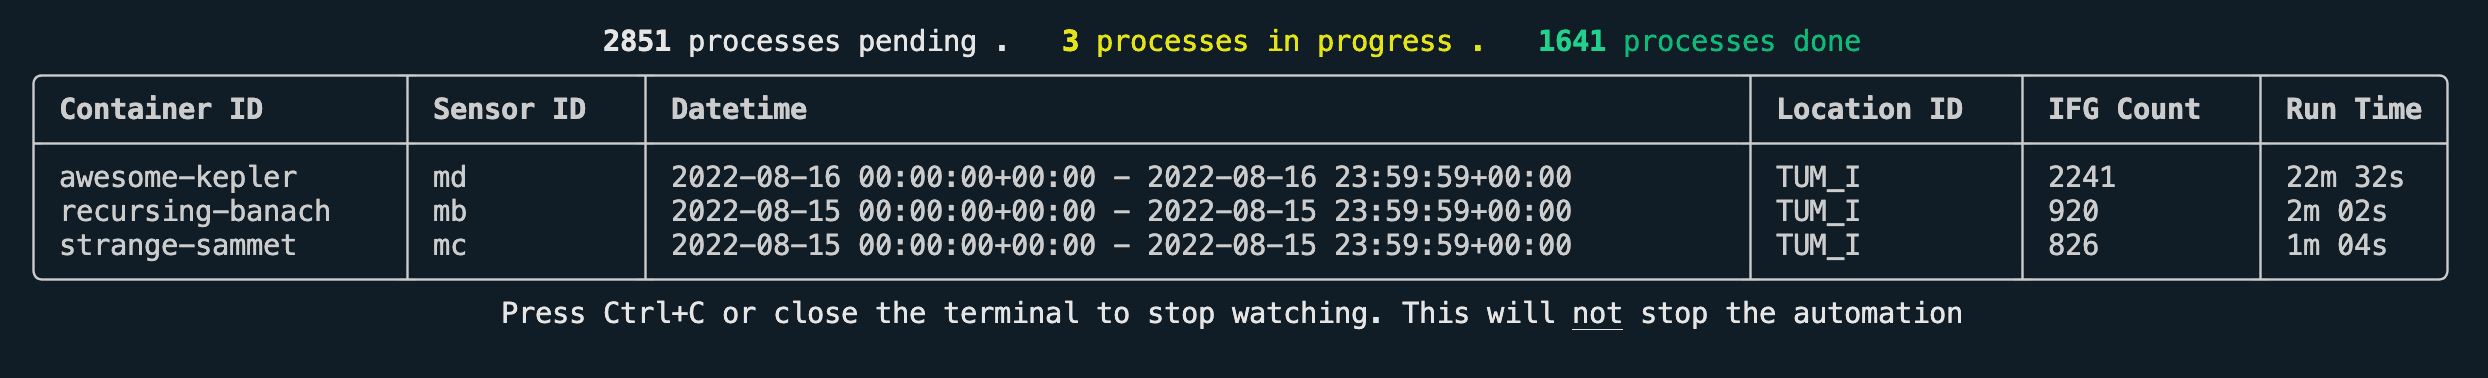
Terminate the ongoing retrievals using the following command:
python cli.py retrieval stopBundling All Retrieval Outputs
Section titled “Bundling All Retrieval Outputs”Bundle all the retrieval outputs using the following command:
python cli.py bundle runYou can specify multiple [[bundle_exports]] entries in config.toml; the command processes each configured export.
Generating GEOMS-compliant HDF5 files
Section titled “Generating GEOMS-compliant HDF5 files”The Generic Earth Observation Metadata Standard (GEOMS) is a standard for exchanging ground-based total-column concentration data. It uses the HDF5 file format and enforces a specific structure for the data (see guidelines from EVDC).
This pipeline can generate GEOMS-compliant HDF5 files from retrieval outputs. Add one or more [[geoms_exports]] entries to config.toml to define the sensors, algorithms, atmospheric-profile models, time range, and filtering settings to export. The separate geoms_metadata.toml file contains the GEOMS file metadata and calibration factors. See the config.toml reference, geoms_metadata.toml reference, and repository templates for the complete schemas.
As always, the pipeline will tell you if any of your configuration files are invalid. Create the GEOMS files using the following command:
python cli.py geoms runThe logs report which files were generated:
Config is validLoading configurationLoading geoms metadataProcessing proffast-2.4/GGG2020Processing sensor id "ma"Sensor ma: found 1105 results in totalSensor ma: found 173 results within the time range ma/20240501: Generated .../proffast-2.4/GGG2020/ma/successful/20240501/groundbased_ftir.coccon_tum.esm061_munich.tum_20240501t114016z_20240501t171933z_001.h5 ma/20240502: Generated .../proffast-2.4/GGG2020/ma/successful/20240502/groundbased_ftir.coccon_tum.esm061_munich.tum_20240502t070418z_20240502t164544z_001.h5 ma/20240504: Generated .../proffast-2.4/GGG2020/ma/successful/20240504/groundbased_ftir.coccon_tum.esm061_munich.tum_20240504t053204z_20240504t171926z_001.h5 ma/20240505: Generated .../proffast-2.4/GGG2020/ma/successful/20240505/groundbased_ftir.coccon_tum.esm061_munich.tum_20240505t051558z_20240505t172421z_001.h5 ma/20240506: Generated .../proffast-2.4/GGG2020/ma/successful/20240506/groundbased_ftir.coccon_tum.esm061_munich.tum_20240506t052157z_20240506t125438z_001.h5 ma/20240507: Not enough data (less than 11 datapoints) ma/20240509: Generated .../proffast-2.4/GGG2020/ma/successful/20240509/groundbased_ftir.coccon_tum.esm061_munich.tum_20240509t072631z_20240509t152931z_001.h5 ma/20240510: Generated .../proffast-2.4/GGG2020/ma/successful/20240510/groundbased_ftir.coccon_tum.esm061_munich.tum_20240510t061155z_20240510t083149z_001.h5ma/20240511: 5%|██████ | 8/173 [00:19<03:07, 1.20s/it]You can verify the integrity of these HDF5 files using the AVDC’s Quality Assurance Tool or NILU’s GEOMS File Format Checker.
Generate a Data Report
Section titled “Generate a Data Report”You can generate a report about the data on your system using the following command:
python cli.py data-reportThis command produces one CSV file per sensor ID in the data/reports/ directory. For example:
from_datetime,to_datetime,location_id,interferograms,ground_pressure,ggg2014_profiles,ggg2014_proffast_10_outputs,ggg2014_proffast_22_outputs,ggg2014_proffast_23_outputs,ggg2020_profiles,ggg2020_proffast_22_outputs,ggg2020_proffast_23_outputs2023-09-07T00:00:00+0000,2023-09-07T23:59:59+0000, TUM_I, 2224, 1440,✅,-,✅,✅,✅,-,✅2023-09-08T00:00:00+0000,2023-09-08T23:59:59+0000, TUM_I, 2178, 1440,✅,-,✅,✅,✅,-,✅2023-09-09T00:00:00+0000,2023-09-09T23:59:59+0000, TUM_I, 1966, 1440,✅,-,✅,✅,✅,-,✅2023-09-10T00:00:00+0000,2023-09-10T23:59:59+0000, TUM_I, 2034, 1440,✅,-,✅,✅,✅,-,✅2023-09-11T00:00:00+0000,2023-09-11T23:59:59+0000, TUM_I, 2122, 1440,✅,-,✅,✅,✅,-,✅2023-09-12T00:00:00+0000,2023-09-12T23:59:59+0000, TUM_I, 1972, 1440,✅,-,✅,✅,✅,-,✅2023-09-13T00:00:00+0000,2023-09-13T23:59:59+0000, TUM_I, 216, 1439,✅,-,✅,✅,✅,-,✅2023-09-14T00:00:00+0000,2023-09-14T23:59:59+0000, TUM_I, 762, 1440,✅,-,✅,✅,✅,-,✅2023-09-15T00:00:00+0000,2023-09-15T23:59:59+0000, TUM_I, 1507, 1440,✅,-,✅,✅,✅,-,✅2023-09-16T00:00:00+0000,2023-09-16T23:59:59+0000, TUM_I, 2232, 1440,✅,-,✅,✅,✅,-,✅2023-09-17T00:00:00+0000,2023-09-17T23:59:59+0000, TUM_I, 1599, 1440,✅,-,✅,✅,✅,-,✅2023-09-18T00:00:00+0000,2023-09-18T23:59:59+0000, TUM_I, 228, 1440,✅,-,✅,✅,✅,-,✅The interferograms and ground_pressure columns contain the number of interferograms and ground-pressure rows found for the respective day. Retrieval and profile columns use ✅ for present data, ❌ for failed retrievals, and - when no data is present.
Running the Retrieval on a Cluster
Section titled “Running the Retrieval on a Cluster”You can of course run this pipeline on a computing cluster (e.g. SLURM-based).
Since the python cli.py retrieval start command terminates after starting the
pipeline in the background, any compute node would also terminate right away.
Therefore, you have to call the underlying main.py script of the
retrieval module: python src/retrieval/main.py.
We use the following SLURM script on CoolMUC-4 at LRZ:
#!/bin/bash#SBATCH -J erp#SBATCH -o /path/to/em27-retrieval-pipeline/data/logs/%x.%j.%N.out#SBATCH -D /path/to/em27-retrieval-pipeline#SBATCH --clusters=cm4#SBATCH --partition=cm4_tiny#SBATCH --qos=cm4_tiny#SBATCH --time=06:00:00#SBATCH --nodes=1#SBATCH --cpus-per-task=112#SBATCH --export=NONE#SBATCH --get-user-env#SBATCH --mail-type=all#SBATCH --mail-user=you@example.com
# setup environment: git is used to determine the commit hash of the currently# running pipeline, gfortran (GCC) is used to compile PROFFAST and the IFG# corruption filtermodule load slurm_setupmodule load gitmodule load gcc/13.2.0
# activate virtual environment: we set up the virtual environment on the login# nodes, but you can also do that inside the compute nodessource .venv/bin/activate
# run retrievalpython src/retrieval/main.py
Dispatch it with SLURM using:
sbatch cm4.sh # using your script nameAs of pipeline version 1.6.2, the retrieval watcher also works when the retrieval process is
running on a separate node using the --cluster-mode flag:
python cli.py retrieval watch --cluster-modeDon’t forget to increase the number of parallel processes of the pipeline with
config.retrieval.general.max_process_count 😉. We run 100 retrievals in parallel
on CoolMUC-4.